



An automated logistic control system is no longer limited to conveyor coordination; it is the operational layer connecting yard movements, loading sequences, equipment availability, and real-time material flow.
For technical evaluators, the central question is whether that layer can make independent assets behave like one predictable, safe, and measurable logistics operation.
The answer depends less on dashboard appearance than on control architecture, data quality, failure behavior, scheduling logic, and the boundaries between operational technology and enterprise systems.
This article explains how synchronization works across conveyors, yards, and loading points, while providing practical criteria for evaluating throughput, resilience, safety, integration effort, and lifecycle value.
What Technical Evaluators Should Assess First
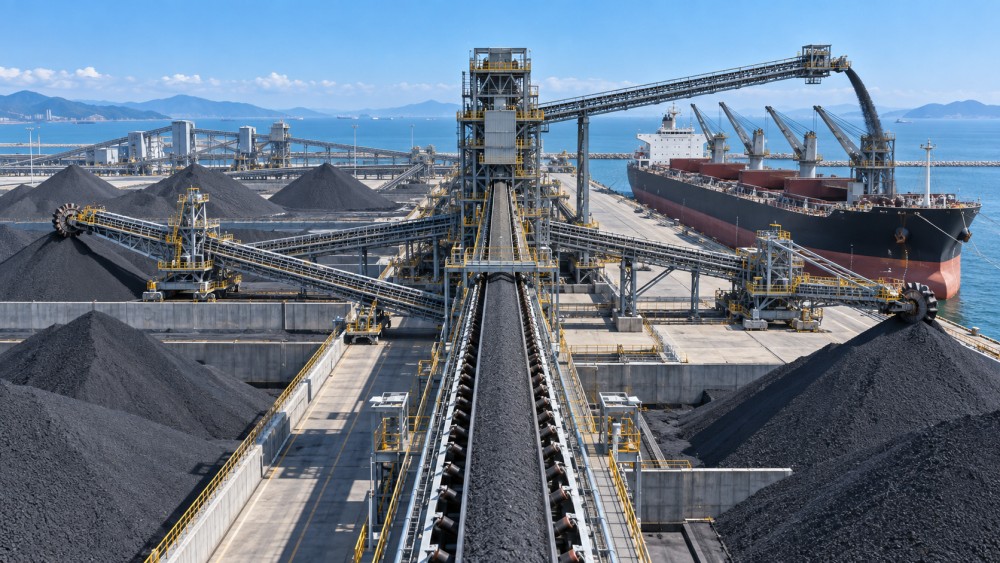
Before reviewing vendors, evaluators should define the physical process that requires synchronization, including material types, transport paths, operating windows, transfer constraints, and planned expansion scenarios.
An automated logistic control system should be assessed as a coordination platform, not merely as a supervisory interface placed above existing PLC and SCADA layers.
The key evaluation issue is decision ownership. Teams must identify which decisions remain local, which require central optimization, and which demand operator authorization during exceptions.
Local control remains essential for machine protection, emergency stopping, drive sequencing, and safe fallback actions when network connectivity or higher-level services become unavailable.
Centralized logic is most valuable where one asset’s action affects another asset’s capacity, such as route allocation, stockpile selection, berth loading, or yard release timing.
Technical evaluators should also distinguish between real-time control requirements and planning requirements. Combining both without clear timing rules often creates unstable, difficult-to-maintain systems.
A practical assessment starts with measurable operational outcomes: tonnes per hour, container moves, truck turnaround time, queue length, energy use, loading accuracy, and recovery time.
If a proposed system cannot connect its functions to those measures, its claimed automation value remains difficult to validate during factory acceptance, commissioning, or operations.
The Control Architecture Behind Synchronization
Synchronization normally follows a layered architecture. Field devices observe physical conditions, PLCs execute deterministic machine logic, supervisory systems coordinate zones, and optimization services manage broader operational priorities.
At the field layer, sensors confirm belt speed, material presence, chute blockage, position, weight, vibration, gate status, machine availability, and safety circuit condition.
PLCs transform those signals into dependable equipment behavior. They start and stop drives, enforce interlocks, manage local sequences, and protect machinery against mechanical or process damage.
Above PLCs, SCADA or HMI platforms provide visualization, alarms, trends, manual intervention functions, and local supervisory commands for control room operators and maintenance teams.
The automated logistic control system uses equipment states and process data to coordinate multiple zones. It determines whether material can move, where it should go, and when loading may begin.
Its scheduling engine must understand both physical constraints and commercial priorities. A loading order cannot be executed simply because it appears first in an enterprise queue.
For example, a vessel may have an urgent loading window, while its allocated stockpile is temporarily unavailable because reclaimers, transfer conveyors, or dust suppression systems are occupied.
Reliable synchronization requires a common operational model. Assets, routes, capacities, permitted materials, operating modes, and maintenance restrictions must be represented consistently across connected applications.
Without that shared model, systems exchange messages but cannot make dependable coordinated decisions. Integration then becomes a collection of interfaces rather than an operating architecture.
How Conveyor Networks Maintain Continuous Material Flow
Conveyor synchronization is often the first visible function, but its importance goes beyond sequential motor starting. It establishes stable flow conditions for downstream storage, loading, and dispatch operations.
A control system must evaluate route availability before releasing material. Every conveyor, transfer tower, chute, diverter, feeder, and receiving point must be compatible with the intended movement.
Route reservation prevents conflicting movements from entering shared equipment. This matters especially in bulk terminals, mines, and industrial hubs where several product grades share transfer infrastructure.
Start-up sequences typically operate downstream to upstream. This ensures receiving equipment is running before upstream feeders discharge material into a route that cannot yet accept it.
Shutdown sequences usually follow the opposite logic, allowing conveyors to clear residual material before downstream machinery stops. Incorrect sequencing creates carryback, blockage, spillage, and cleaning burdens.
Speed control is another important synchronization mechanism. Variable-speed drives can match upstream feed rates with downstream capacity, reducing surges, belt loading, and unnecessary energy consumption.
Mass-flow data from belt scales, feeders, and volumetric sensors allows the system to adjust rates dynamically. Evaluators should examine measurement accuracy, filtering, calibration practices, and degraded-mode behavior.
Material tracking becomes critical when different grades, moisture levels, contamination restrictions, or customer specifications apply. The system must preserve product identity through blending, storage, reclaiming, and loading.
Technical teams should verify how the platform handles uncertainty. Lost sensor signals, delayed updates, manual bypasses, and unplanned conveyor stops must not silently corrupt material inventory records.
Synchronizing Yard Operations With Process Demand
Yards introduce a different control problem because equipment movement is spatial, variable, and often affected by weather, traffic, labor availability, maintenance work, and changing dispatch priorities.
In container environments, synchronization may involve automated stacking cranes, terminal tractors, rail-mounted gantries, gate systems, quay cranes, and yard planning applications operating simultaneously.
In bulk logistics environments, yard coordination can include stackers, reclaimers, mobile equipment, stockpile zones, rail unloading stations, transfer conveyors, and ship or train loaders.
The automated logistic control system converts operational demand into executable work. It decides which equipment receives a task, which route is reserved, and what sequence minimizes conflict.
Task assignment should account for location, travel time, equipment capability, battery or fuel status, maintenance restrictions, congestion, and the downstream deadline associated with each movement.
Simple first-come, first-served rules may appear fair but often reduce throughput. Better scheduling balances service priorities with physical travel paths and constraints at shared transfer points.
Yard synchronization also depends on geofencing, positioning confidence, and traffic management. A tasking engine cannot safely optimize movements when machine location data is inconsistent or delayed.
Evaluators should ask whether the system supports progressive deployment. Many sites require mixed fleets where automated, remote-operated, and manually driven assets coexist for extended periods.
A mature design manages that coexistence explicitly, including exclusion zones, handover procedures, confirmation points, and reduced-speed rules. It should not treat manual activity as an exceptional condition.
Loading Control Requires Sequence, Accuracy, and Safety
Loading is where upstream synchronization becomes commercially visible. A shiploader, train loader, truck station, or container crane must receive the correct material or unit at the required time.
Loading sequences must incorporate physical readiness checks. These include berth availability, vehicle position, hatch alignment, load limits, trim plans, weighbridge status, dust controls, and communication permissions.
For bulk loading, the control platform may coordinate reclaiming, conveying, sampling, weighing, and loading spouts. Each stage must remain synchronized as rate and destination conditions change.
For container loading, the process combines stowage instructions, crane work queues, yard delivery timing, equipment availability, and safe separation between vehicles, cranes, and personnel.
Loading accuracy requires reliable reconciliation. The system should compare planned quantity, dispatched quantity, measured quantity, and acknowledged quantity while preserving a traceable record of deviations.
Technical evaluators should inspect how loading rules are changed. Recipe management, version control, role-based approval, testing environments, and audit trails are necessary for controlled operational changes.
Safety logic must remain independent from productivity logic where appropriate. A scheduling engine may request a loading action, but certified safety systems must determine whether movement is permitted.
This separation protects the operation when optimization software fails, communications are interrupted, or an incorrect master-data value creates an invalid instruction for field equipment.
Integration Quality Determines the Real Value
Most projects fail to deliver expected value because integration assumptions are weak. A strong automated logistic control system requires dependable connections, clear ownership, and well-defined data semantics.
Typical interfaces include PLC networks, SCADA platforms, maintenance systems, terminal operating systems, warehouse systems, enterprise resource planning, laboratory systems, weighbridges, and fleet management tools.
Evaluators should map every interface by purpose rather than merely by protocol. Knowing that OPC UA, MQTT, REST, or Modbus is used does not explain operational responsibility.
For each data exchange, define the source of truth, update frequency, expected latency, validation rules, failure response, retry mechanism, and the authority to correct inaccurate information.
Real-time operational data needs deterministic handling, but planning data can often tolerate longer cycles. Confusing these categories increases network load and creates unrealistic availability expectations.
Master data deserves special attention. Equipment identifiers, product codes, route definitions, capacities, dimensions, hazardous-material rules, and operational calendars must remain aligned across systems.
Integration testing should include abnormal conditions, not only successful messages. Test communication loss, duplicate commands, stale records, partial acknowledgements, timing conflicts, and restoration after system restart.
Cybersecurity must be included from the architecture stage. Segmentation, identity management, patching responsibilities, remote access controls, event logging, and vendor support channels require explicit governance.
Sites should avoid excessive dependence on undocumented point-to-point interfaces. They can accelerate early deployment but become expensive when equipment changes, software upgrades, or new operational scenarios emerge.
Evaluating Throughput, Reliability, and Exception Handling
Throughput claims should be tested against realistic constraints rather than nameplate equipment capacity. The relevant measure is sustained output during normal variability, planned transitions, and credible disturbances.
Simulation can help evaluate proposed control strategies, particularly where multiple routes, shared assets, tide windows, train arrivals, or uneven product availability create complex interactions.
However, simulation results are only credible when input assumptions are transparent. Evaluators should review failure distributions, changeover times, operator interventions, sensor accuracy, and congestion assumptions.
Reliability should be assessed as an operational chain. A highly available scheduling server offers little value if a weak field network or poorly maintained sensor repeatedly blocks execution.
Mean time to recover is often more informative than mean time between failures. The system should help operators identify the affected zone, understand the constraint, and restore service safely.
Exception management must be designed around real working conditions. Operators need prioritized alarms, clear recommended actions, escalation paths, and the ability to place equipment into controlled manual modes.
A useful evaluation scenario asks what happens when a critical conveyor trips during vessel loading. The answer should cover containment, rerouting, inventory integrity, rescheduling, and communication with stakeholders.
Another scenario concerns unavailable yard equipment. The platform should reassign work intelligently while respecting safety zones, service commitments, equipment limitations, and any material segregation requirements.
Systems that only optimize normal operations may create greater disruption during incidents. Resilience comes from transparent fallback logic and rapid recovery, not simply from sophisticated algorithms.
Implementation Risks and Practical Acceptance Criteria
Implementation risk is highest when operating procedures, control logic, data ownership, and equipment readiness are addressed separately. Successful projects align these elements before commissioning begins.
Technical evaluators should require a requirements traceability matrix linking operational objectives to functional requirements, interfaces, control narratives, test cases, performance criteria, and responsible parties.
Factory acceptance testing should validate control sequences, interlocks, alarms, integrations, and operator workflows using representative scenarios. It should not be limited to isolated screen demonstrations.
Site acceptance testing must confirm physical behavior under real signals, communications delays, equipment limitations, and operational staffing conditions. Commissioning plans need measurable release gates for each area.
Performance acceptance criteria should include sustained throughput, loading accuracy, task completion times, route availability, alarm response, inventory reconciliation, and recovery after defined equipment failures.
Change management is equally important. Dispatchers, maintenance technicians, control room operators, planners, and safety teams need role-specific procedures that match the automated operating model.
Training should use realistic disruptions rather than only normal workflows. Operators must understand how to intervene, when to override automation, and how to return the plant safely to coordinated control.
Lifecycle evaluation should include software support, spare hardware, cybersecurity updates, configuration ownership, documentation quality, and the availability of engineers capable of maintaining the operational model.
Choosing the Right Scope for an Automated Logistic Control System
Not every logistics site needs a fully centralized optimization platform immediately. The appropriate scope depends on process complexity, current bottlenecks, integration maturity, operational volatility, and expansion plans.
Sites with stable single-route operations may gain value first from improved PLC standards, condition monitoring, and supervisory visibility before deploying advanced scheduling or yard optimization functions.
Complex terminals benefit more quickly when several independent assets compete for shared routes, loading points, storage areas, or limited operating windows throughout the day.
A phased deployment can reduce risk. Establish reliable asset states and route control first, then add task orchestration, optimization, predictive maintenance insights, and enterprise-level planning integration.
The platform should support this progression without forcing a complete redesign. Open interfaces, modular services, consistent asset models, and controlled configuration management are important selection criteria.
Technical evaluators should challenge vendors to demonstrate real workflows using the site’s operational constraints. Generic architecture diagrams are useful, but scenario-based proof provides stronger evidence.
Ask how the system handles blocked routes, changing loading priorities, missing data, manual equipment takeover, constrained storage, and delayed arrivals. These cases reveal its practical operating maturity.
Conclusion: Synchronization Is an Operational Capability
An automated logistic control system creates value when it turns conveyors, yards, and loading assets into a coordinated operating system rather than a collection of individually automated machines.
For technical evaluators, the strongest solutions demonstrate clear decision boundaries, dependable field integration, transparent scheduling, safe fallback behavior, measurable performance, and maintainable lifecycle governance.
The most important judgment is not whether the platform contains advanced algorithms. It is whether those algorithms remain trustworthy when physical conditions, equipment states, and commercial priorities change.
By evaluating architecture, data quality, exception handling, acceptance criteria, and phased deployment options together, logistics organizations can select automation that improves both operational efficiency and control confidence.